Haoran (Jensen) Yuan
PhD Student · Computer Engineering · University of Illinois Urbana-Champaign
My research focuses on efficient AI, especially on how to make embodied AI generalizable, scalable, and efficient. I build visuo-tactile world-action models that adapt pretrained video models to touch without separate tactile pretraining, letting robots reason about contact that cameras cannot see. I also develop lossless parallel drafting methods that speed up large-model inference several times without changing its outputs. I am also interested in representation learning and recursive self-improvement (RSI), and I am currently exploring agentic robotics and reinforcement learning for world-action models.
I am a PhD student in PLAN Lab at UIUC, advised by Prof. Ismini Lourentzou. I have also worked with BAIR at UC Berkeley and Hao AI Lab at UC San Diego. Before my PhD, I received an M.S. in Computer Engineering from UIUC, a dual B.S. from UIUC and Zhejiang University, and interned as a software engineer at Snowflake.
News
- 2026-10 Released JetSpec++! The paper and code are now public.
- 2026-09 Released DexTacWAM! The paper, code, model weights & data and website are now public. Featured by BAIR.
- 2026-08 Started my Ph.D. in Computer Engineering at UIUC, advised by Prof. Ismini Lourentzou.
- 2026-06 Released JetSpec! The paper, code, models and website are now public. Featured by Hao AI Lab.
- 2026-03 Released VTAM! The paper and website are now public.
Research Experience
Education
Research
* equal contribution · † project lead · ‡ equal advising · highlighted papers are projects I led
Extends a video diffusion world model with fingertip touch on a 22-DoF bimanual robot so it can predict contact the cameras cannot see. Reaches 70.6% average success on six real-robot tasks, against 38.0% for the strongest baseline.
Adds tactile streams to a pretrained video transformer through lightweight modality-transfer fine-tuning, with a tactile regularization loss that keeps vision from dominating. Reaches 90% average success on contact-rich tasks such as chip pick-and-place and cucumber peeling.
Conditions each drafted token on its full branch history and pre-drafts the next block during verification. Up to 7.45× faster than autoregressive decoding and 1.54× faster than DSpark on Qwen3-8B.
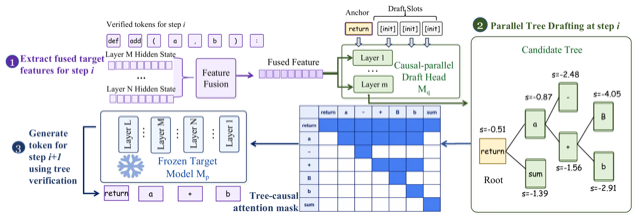
A causal draft head that emits a full speculative tree in one forward pass while keeping the target model's autoregressive factorization along every branch. Up to 9.64× end-to-end speedup on Qwen3-8B (MATH-500).